Effective AI Rollout for Service Industries
AI Implementation, Business Strategy, Service Industry AI, Pilot Project Success
A Practical Method for Rolling Out AI Without Wrecking Your Operations
Most failed AI Implementation efforts do not collapse because the technology is bad. They fail because the rollout strategy is vague, overloaded, or both. For high-volume service businesses and agencies, the real risk is not “AI gone rogue” but pilots that never end or full-stack launches that implode under their own complexity. This article lays out a concrete, low-drama method Bot-Brand uses to deploy Service Industry AI that avoids both traps while aligning tightly with Business Strategy and measurable outcomes.
The Two Failure Modes of AI Rollouts
When Bot-Brand audits broken AI projects, two patterns show up almost every time:
The pilot that never ends. Nobody defined success upfront, so the “experiment” drifts for months. Scope creeps, teams lose interest, and leadership quietly stops asking for updates. The AI remains a curiosity, not infrastructure.
The everything-at-once launch. Eleven moving parts go live on day one: website AI, phone AI, CRM automation, routing logic, and new reports. Something breaks, but with so many dependencies, nobody can say which piece failed. The safest move is rollback, and AI is labeled “too risky” for another year.
Avoiding these outcomes requires a disciplined method: choose one tightly defined use case, measure it ruthlessly, and run a time-boxed pilot with a written exit. That is the core of a reliable AI Implementation strategy for serious operators.
Four Project Evaluation Questions for Your First AI Use Case
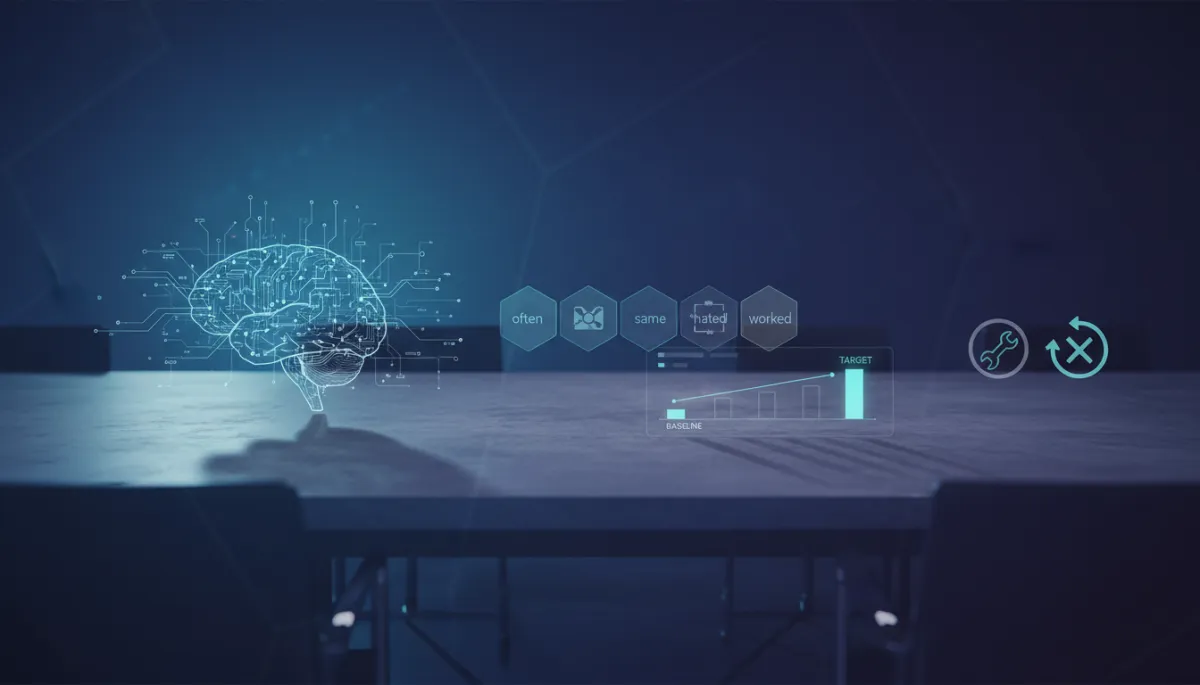
Your first AI project should not be visionary; it should be boring, repetitive, and measurable. Bot-Brand uses four simple Project Evaluation Questions to select that first use case:
Does it happen often? If the process only occurs a few times a month, you will not see meaningful impact or enough data to tune the system. High-frequency tasks generate faster learning and clearer ROI.
Is it the same every time? Variability is the enemy of early pilots. Look for workflows with consistent inputs and outputs: standard questions, standard forms, standard next steps. Consistency lets your AI logic and prompts stabilize quickly.
Does somebody hate doing it? This is where adoption lives. When your team dislikes a task—repetitive intake calls, form-filling, basic follow-ups—they are more likely to champion AI support, not resist it. Morale lift is a real business benefit.
Can you tell whether it worked? If you cannot say “this interaction succeeded” or “it failed,” you cannot improve or justify expansion. The outcome needs to be observable and countable: booked appointment, qualified lead, resolved ticket, payment collected.
If a candidate use case does not pass all four questions, it is not your first AI project. Save complex, edge-heavy workflows for later cycles, after your organization has proven it can run and evaluate a narrow pilot.
Clear selection criteria prevent your first AI project from becoming an unfocused experiment.
Why First-Response Is the Best Starting Point for Service Businesses
For most service businesses and agencies, the ideal first use case is first-response—the initial interaction when a lead, prospect, or client reaches out. That can be an inbound call, web chat, form submission, or social message. It almost always satisfies the four questions:
It happens often: high-volume local services may see dozens or hundreds of inbound touches per day.
It is largely the same every time: “What do you charge?”, “Do you service my area?”, “Can I book an appointment?”.
Staff often hate the constant interruption and repetition of answering basic questions and scheduling.
You can clearly tell whether it worked: Did we capture the lead? Did we qualify them? Did we book a slot?
Bot-Brand’s Neural Intercept Protocol is designed specifically for this top-of-funnel first-response layer. By intercepting, qualifying, and synchronizing leads 24/7 with human-grade inflection, you convert more inbound interest while freeing your team from constant manual triage. Crucially, first-response is measurable and bounded, which makes it ideal for a disciplined pilot instead of an uncontrolled overhaul.
Start With a Measured Baseline (Counted by Hand if Necessary)
Before a single AI message is sent or a single voice flow goes live, you need a Measured Baseline. This is the step most teams skip, and it is why they cannot prove Pilot Project Success even when the system works.
For a first-response pilot, your baseline might include:
Average time-to-first-response during business hours and after-hours
Percentage of inbound leads that receive no response within 24 hours
Conversion rate from inbound contact to booked appointment or qualified opportunity
If your systems cannot currently report this, count manually for a week. Export call logs, review inboxes, and tally outcomes in a spreadsheet. It is tedious, but it gives you the only thing that matters: a concrete “before” picture. Without it, you are left with opinions, not evidence, and your AI Implementation becomes a story, not a strategy.
💡 Professional Note: A baseline is not a guess. It is a written, dated snapshot of how the process performs today, even if you had to build it by hand.
Even a hand-counted baseline outperforms a vague sense that “things will improve.”
Set a Target Specific Enough to Be Wrong
Once you have a baseline, define a target that is specific enough to be wrong. “Improve response times” is not a target. “Cut average time-to-first-response from 3 hours to under 5 minutes for 80% of inbound leads within 30 days” is. You can miss it. You can exceed it. You can learn from it.
This is where Business Strategy meets operational reality. Your target should be ambitious enough to justify the work, but not so extreme that it demands a risky, all-or-nothing launch. Bot-Brand typically aligns targets with clear business levers: more booked jobs, higher show-up rates, faster ticket resolution, or fewer missed calls.
The Step Almost Nobody Takes: A Written Exit Condition
Careful operators are not afraid of AI. They are afraid of systems they cannot turn off. The antidote is a written exit condition: a clear statement, agreed in advance, of what result would make you shut the pilot down.
For example:
“If more than 5% of AI-handled interactions result in a documented complaint about rudeness or confusion, we turn it off.”
“If booked appointments from AI-handled leads fall below 70% of our human-handled conversion rate for two consecutive weeks, we turn it off.”
This written exit is what makes prudent executives and operations leaders willing to engage. They are not committing to permanent autonomy; they are authorizing a reversible experiment with guardrails. For Bot-Brand, this is non-negotiable. It aligns with our values of precision logic, architectural integrity, and controlled scaling rather than blind disruption.
Predefined exit rules convert AI from a gamble into a controlled business experiment.
The 30-Day Narrow Run: How to Pilot Without Chaos
With your first-response use case selected, your Measured Baseline recorded, your target defined, and your exit condition written, you are ready for a 30-day narrow run. This is a constrained, production-adjacent pilot with two simple rules that keep it safe and useful.
Rule 1: Someone Reads Actual Transcripts Twice a Week
AI dashboards are helpful, but they do not replace human judgment. Twice a week, a designated owner—often an operations manager or account lead—should read a sample of real transcripts or call summaries from AI-handled interactions. They are looking for:
Obvious misunderstandings of your services, pricing, or policies
Repeated edge cases that might require a new rule or handoff path
Tone issues severe enough to trigger your exit condition
This simple practice keeps your AI grounded in reality and ensures that your Neural Intercept layer continues to feel human-grade, not robotic or off-brand.
Rule 2: Week One Fixes Scope, Not Tone
The most common mistake in early pilots is obsessing over tone in the first few days. Leaders want the AI to sound perfect before it is even reliably doing the right work. In week one, your only priority is scope:
Is the AI handling only the scenarios you agreed on?
Does it hand off to humans correctly when outside that scope?
Are the core actions (booking, qualifying, routing) happening consistently?
Once scope is locked, you can refine tone, phrasing, and brand voice in weeks two and three. This sequencing protects you from endless cosmetic tweaks while the underlying workflow remains unstable.

Reviewing real interactions twice weekly keeps your pilot aligned with real customer expectations.
Day 30: Decide Out Loud — Expand, One More Cycle, or Turn It Off
At the end of 30 days, you do not “see how it goes.” You make an explicit, out-loud decision with the stakeholders who own the process. There are only three options:
Expand. The pilot hit or exceeded your target without triggering the exit condition. You commit to widening scope—more channels, more hours, or more use cases—using the same disciplined method.
One more 30-day cycle. Results are promising but not definitive. You adjust prompts, routing, or measurement, then run another time-boxed cycle with the same rigor.
Turn it off. You hit the exit condition or missed the target badly enough that further effort is not justified. You shut the pilot down, document what you learned, and preserve organizational trust.
This explicit decision point prevents the “pilot that never ends” and reinforces that AI is part of serious Business Strategy, not a side project. It also demonstrates to your teams that autonomy is earned through evidence and integrity, not hype.
From Pilot Project Success to Autonomous Infrastructure
When you run AI pilots this way—tight scope, Measured Baseline, specific targets, written exits, and a 30-day narrow run—you create a repeatable pattern. Each successful cycle justifies the next layer of autonomy: more channels, deeper workflows, richer data integration. Over time, you move from isolated experiments to the kind of 24/7 autonomous operational infrastructure that Bot-Brand promises: systems that intercept, qualify, and synchronize leads with zero manual intervention, while still operating inside clear business guardrails.
If you are ready to move beyond AI curiosity and into controlled, evidence-based deployment across your service operations, Bot-Brand can help architect the path. We bring precision logic, technical integrity, and a proven rollout method designed for high-volume environments where failure is not an option.
Initialize a Secure Uplink for an Architectural Audit and Systems Diagnostic, and we will map exactly how to take your first-response workflows from manual bottleneck to autonomous Neural Intercept—without the pilots that never end or the launches that crash on day three.