Effective AI Rollout for Service Operations
AI Rollout, Service Operations, Bot-Brand
A Practical Method for Rolling Out AI Without Burning Your Business
Most AI failures in service businesses aren’t technical. They’re operational: pilots that never end, or chaotic, everything-at-once launches that get rolled back in a panic. This article lays out a disciplined, low-drama way to roll out AI in your business, used by Bot-Brand when we deploy autonomous voice and chat agents for high-volume service operators.
The Two Failure Modes You Must Avoid
When owners tell us “AI didn’t work for us,” the story is almost always one of two patterns:
The pilot that never ends. Someone turned on an AI tool, but nobody wrote down what success meant. Months later, people are still “trying it,” no one can say if it’s helping, and the project quietly dies—or worse, quietly lingers, burning time and attention.
The everything-at-once launch. Eleven things change on day one: new AI agent, new phone routing, new CRM fields, new scripts, new reporting. Something breaks, customers complain, and because nobody can see which piece failed, leadership rolls the whole thing back.
Bot-Brand’s methodology is designed to make both of those impossible. It starts with choosing one tightly defined first project, then running a 30-day narrow test with clear entry and exit conditions.
Choosing the First AI Project: Four Simple Questions
Your first AI deployment should not be the most glamorous idea. It should be the most testable. Use these four questions as a hard filter:
Does it happen often? If the task only happens a few times a month, you won’t get enough data to learn anything in 30 days. Think dozens or hundreds of occurrences per week: inbound calls, quote requests, appointment reminders, intake forms, follow-up emails.
Is it basically the same every time? AI loves structured workflows. “Capture name, contact info, service type, and preferred time” is perfect. “Figure out a custom strategy for each client” is not a first project. You want clear steps, clear fields, and minimal branching logic.
Does somebody hate doing it? If your team dreads this task, you get an automatic win on morale. Think of late-night call-backs, repetitive data entry, or chasing no-show leads. A project people actively dislike is easier to adopt and easier to defend when you’re tuning the system.
Can you tell whether it worked? If you can’t say “this worked” or “this didn’t” in a sentence with a number, it’s not a good starting point. You need a clear, observable outcome: booked appointments, answered calls, qualified leads, scheduled jobs, first-contact resolution.
💡 Pro Tip: If a candidate project fails any one of these four questions, park it for later. Your first AI win should be boring, measurable, and repetitive.
Why “First Response” Is the Best Starting Point for Service Businesses
For high-volume local service businesses—plumbing, HVAC, dental, legal, home services, clinics—there is one workflow that usually passes all four tests: first response to an inbound lead or inquiry.
It happens constantly: calls, forms, chats, messages, emails.
It’s structurally similar every time: acknowledge, qualify, capture details, offer times, confirm next step.
Staff usually dislike it when it’s after-hours, during peak crunch, or when the lead is obviously unqualified.
It has a clean outcome: did we capture and qualify the lead and move them to a booked slot or a clear status, yes or no?
Bot-Brand’s Neural Intercept Protocol is built exactly around this moment: intercepting first contact, capturing structured data with human-grade inflection, and syncing it into your systems without human intervention. As a first AI project, it is narrow, high-impact, and extremely measurable.
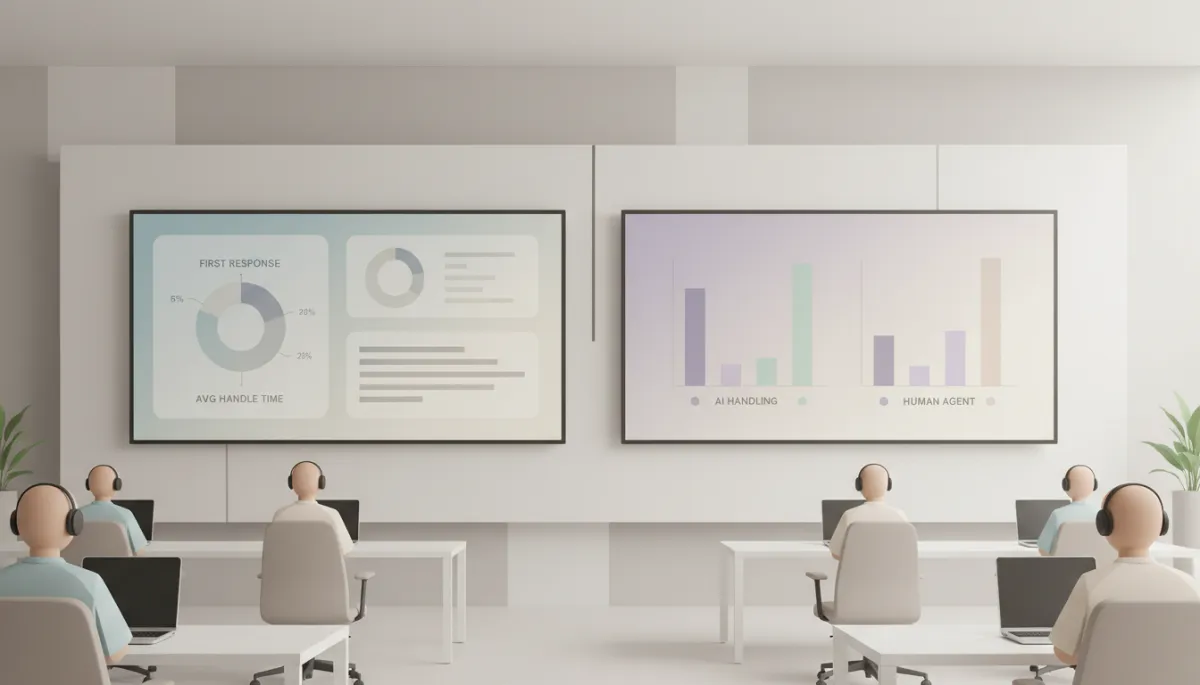
Tracking first-response metrics makes AI performance visible and actionable within days.
Write Down a Baseline Before You Touch Anything
The difference between “we think it’s helping” and “we know it’s helping” is a written baseline. Before you turn on any AI, you must know how the process performs today—even if you have to count it by hand.
For a first-response project, that might be:
Number of inbound leads per day (calls, forms, chats).
Percentage answered within five minutes, within one hour, not answered at all.
Percentage that become booked appointments or qualified opportunities.
If your systems don’t track this cleanly, assign someone to tally it manually for a week. Use a clipboard if you must. The point is not perfection; the point is to have a real number you can compare against later.
📌 Key Takeaway: If you can’t state your current numbers, you’re not ready to judge an AI rollout. Baseline first, then build.
Set a Target Specific Enough to Be Wrong
Vague goals like “improve response times” or “capture more leads” invite endless pilots. To avoid the pilot-that-never-ends, you need a target that is specific enough to be wrong.
For example:
“Increase answered-within-five-minutes from 42% to at least 75% in 30 days.”
“Raise lead-to-booked-appointment from 31% to 40%+ on AI-handled interactions.”
These targets can be hit, missed, or exceeded. That’s the point. A measurable target turns every 30-day run into a clear decision instead of a debate.
Define the Exit Before You Enter: When Will You Turn It Off?
Here is the step almost nobody takes: write down in advance what outcome would make you shut the system off. Not in theory—on paper, before you start.
For a first-response AI agent, that might look like:
“If more than 5% of AI-handled conversations generate a customer complaint about rudeness or confusion in any week, we pause the system and review.”
“If AI-handled leads book at less than 70% of the human baseline for two consecutive weeks, we turn it off and revert to manual handling.”
This written exit is what makes careful operators—and their legal and compliance teams—willing to engage. They are not signing up for an experiment with no brakes. They are signing up for a controlled trial with a clearly marked kill switch.
💡 Pro Tip: Share the exit criteria with your frontline team. Knowing there is a clear off-ramp reduces resistance and increases honest feedback.
The 30-Day Narrow Run: Two Non-Negotiable Rules
With a first project selected, a baseline measured, a target defined, and exit conditions written, you’re ready for a 30-day narrow run. This is not a full rollout; it is a controlled experiment on a slice of traffic, with two strict rules.
Rule #1: Someone Reads Actual Transcripts Twice a Week
Dashboards are not enough. Twice a week, a human owner of the project must read a sample of real AI interactions—calls, chats, messages—end to end. This is where you catch subtle failure patterns long before they show up as complaints or lost revenue:
Repeated questions the AI can’t answer but should.
Confusing phrasing that sounds “off” for your brand voice.
Edge cases where the AI should gracefully hand off to a human sooner.
Rule #2: Week One Fixes Scope, Not Tone
In the first week, you are not polishing personality. You are fixing scope:
What questions the AI is allowed to answer.
Which workflows it owns end-to-end (for example, “new lead intake for plumbing emergencies between 6 p.m. and 8 a.m.”).
When it must hand off to a human, and how that handoff is signaled.
Tone tweaks—friendlier greetings, brand phrases, micro-copy—come later. If the scope is wrong, no amount of tone polishing will save the rollout. By the end of week one, everyone should be clear on “what the AI is allowed to do” and “what it is not allowed to do.”
Day 30: Make an Out-Loud Decision
At the end of the 30-day run, you do not “keep testing.” You gather the baseline, the target, the actual numbers, and a few example transcripts, and you make an explicit, spoken decision in front of the relevant stakeholders. There are only three options:
Expand. The AI met or exceeded the target, stayed within your exit thresholds, and the transcripts look solid. You increase the share of traffic it handles or add a closely related workflow.
One more cycle. The system is promising but short of the target. You identify specific changes—better prompts, tighter scope, improved routing—and commit to a second 30-day run with updated targets.
Turn it off. The AI missed the target and/or violated your exit conditions. You shut it down, document what you learned, and move to a different project. Because the exit criteria were written in advance, this is a clean call, not an argument.
Saying the decision out loud—“we are expanding,” “we are doing one more 30-day cycle,” or “we are turning it off”—prevents the slow slide into endless, undefined pilots.
From One Narrow Win to Autonomous Infrastructure
This method may feel conservative compared to the hype around “AI transformation.” That is intentional. High-volume service businesses do not need theatrics; they need precision logic and operational certainty.
Bot-Brand uses this exact framework to deploy our Neural Intercept Protocol and autonomous voice/chat agents. One narrow, measurable win at the first-response layer becomes the foundation for a broader autonomous ecosystem—follow-up sequences, payment links, rescheduling flows, and more. Each new layer gets the same treatment: clear baseline, specific target, pre-written exit, 30-day narrow run, out-loud decision.
If you want AI to actually replace manual bottlenecks—rather than become a new one—start small, measure hard, and commit to real decisions. That is how you move from experiments to 24/7 autonomous operational infrastructure that intercepts, qualifies, and synchronizes leads with zero human intervention.
Next Step: Initialize a Secure Uplink for an Architectural Audit and Systems Diagnostic with Bot-Brand, and we’ll help you select, baseline, and execute your first 30-day AI run with technical integrity and measurable upside.